What AI says about your market when nobody names the brand.
We measure the answer market of a category: which providers AI names for real buying questions, what those answers rest on and where competitors stand.

Our clients
 Niccos — Shopify & e-commerce
 Touchpoint Amplify — Google Ads agency
 NEONA — Designer lighting & e-commerce
 Ad Specialist — Performance marketing agency
 Insel Gruppe — Bern University Hospital
 Bluerails — Agentic booking for hotels
 voids.ai — Supply-chain SaaS
 SPIELMANN Steuerberatung GmbH — Tax consulting
 PUNKT PR — PR agency
 myAutoAbo — Car subscription comparison
Four steps to a market statement.
From corpus to analysis. Every step is documented and repeatable, because a one-off measurement proves nothing in this channel.
Build the corpus
Real buying questions from sales, service and the market, grouped into intent clusters, each in several phrasings.
Separate branded
Questions without a brand name are analysed separately. Putting your brand in the question measures nothing.
Measure five systems
ChatGPT, Gemini, Perplexity, Claude and Google. They answer differently and from different sources.
Repeat
A fixed benchmark sample runs unchanged in every round. Only comparison across rounds allows a statement.
LLM market research for enterprises in practice.
Documented projects with figure, period and the work behind them.
Niccos - Shopify & e-commerce+761 %
more impressions in 3 months
How a Shopify relaunch led to more organic demand.
NEONA - Designer lighting & e-commerce+315 %
more conversions from AI assistants in 3 months
How a lighting store used Sphen to reach more buyers through ChatGPT, Gemini and Perplexity.
 AGS IT-Service - Healthcare IT
+115 %
more impressions in 4 months
How a clear medical IT site structure doubled visibility in a regulated niche.
What you get and who it fits.
What you get
- Prompt corpus as a file, documented and owned by you
- Market report with mention shares per provider and cluster
- Source landscape: which publications carry the answers
- Gap list: where evidence for your own brand is missing
- Method documentation so the measurement stays repeatable
A fit if
- The category is large enough to have real buying questions with provider choice.
- Someone will make a decision based on the result.
- Repeated measurement is wanted, not just a single number.
Not a fit if
- You want one number for a slide.
- The result is supposed to be known in advance.
- The category is so narrow that no real selection questions exist.
How working with us goes.
Four steps from the first call to ongoing delivery. The process is the same for every service.
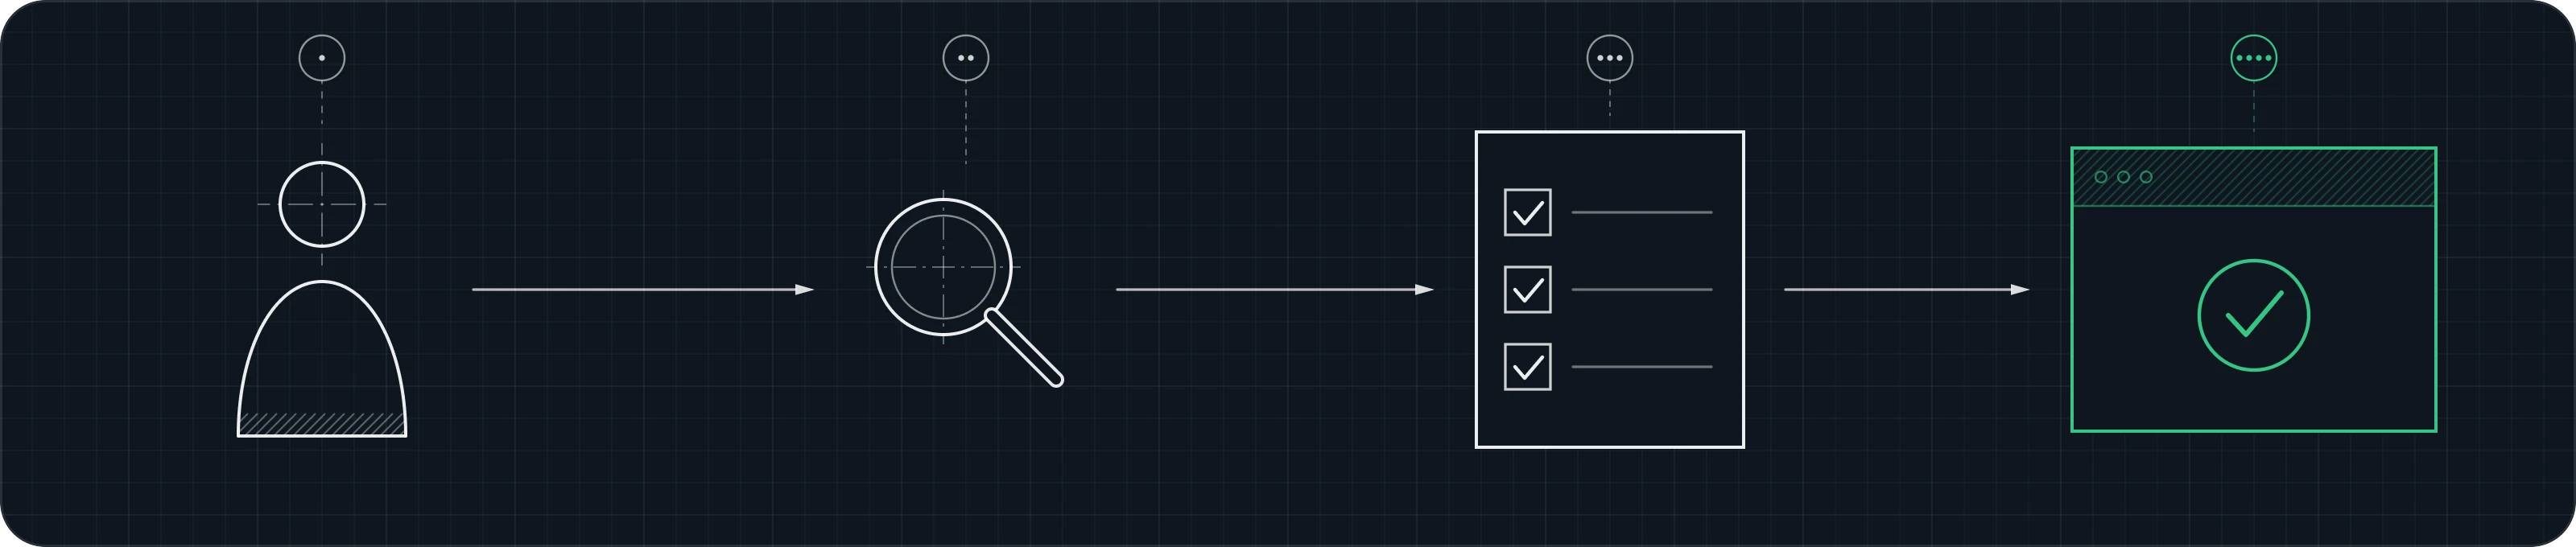
First call
In 15 minutes we clarify your category, your goal and where you stand in Google and in AI answers today.
Analysis
Our platform runs real buying questions through ChatGPT, Gemini, Perplexity, Claude and Google and shows which providers get named and which evidence you are missing.
Plan
You receive a prioritised plan with sequence, effort and expected impact. Then you decide whether we work together.
Delivery
We implement, measure mentions, rankings and traffic every month and report in a shared Slack channel.
What our clients say.
Quotes from founders and managing directors we work with. Where a case exists, the number sits next to it.
“No fuckin way, Felix Ament is the GOAT. Within weeks, NICCOS was #1 on ChatGPT and Claude. Our organic inbound leads have exploded thanks to getSichtbar.”
+761 %
more impressions in 3 months
“In the first month, the first request came in with the line: 'ChatGPT recommended you to me.' That is exactly why we use getSichtbar.”
+980 %
more organic conversions in 3 months

Common questions about LLM market research for enterprises.
How is this different from classic market research?
Classic research surveys people and measures attitudes. We measure what AI systems answer when a buyer asks for providers. It is not a replacement but an additional channel — one where the shortlist now forms before anyone talks to sales.
How many questions does a solid measurement need?
It depends on category breadth. A narrow niche is often covered by 60 to 100 questions across eight to ten clusters. 500 questions pay off when range, personas and use scenarios diverge strongly. More questions are not automatically better, they only cost more measurement runs.
Why not just ask ChatGPT ten times?
Because a single phrasing can decide the outcome, and answers vary by system, model version, region and time. Only spread across many variants and repetition with the same sample turns observations into a statement.
Which systems do you measure?
ChatGPT, Gemini, Perplexity, Claude and Google AI Overviews. Analysis is per system, because answers and cited sources differ markedly — an overall average hides exactly those differences.
Do we get the raw data?
Yes. Prompt corpus, raw answers and analysis belong to you and stay usable if the engagement ends. The method documentation is included so the measurement can be repeated without us.
Is this the same as GEO?
No. This service measures and describes the market. GEO changes your position in it. Many clients start with the measurement because only then can they decide whether and where visibility work pays off.
Do you publish the results?
Only with written approval. Results show one company's position against named competitors; that belongs to the client. Without approval we publish the method and nothing else.
How fast is the first report?
Four to six weeks. Building the corpus takes longest, because it comes from real buying questions rather than a keyword tool. The measurement itself runs in days.
What works together here.
Talk to us about your visibility.
15 minutes, straight from the calendar. Before the call we check which providers AI names in your category and bring the result.
Felix Ament
You talk to me directly.
What happens in the call
- We show which providers ChatGPT, Gemini, Perplexity and Google name for buying questions in your category.
- We show which sources support those answers and where competitors stand.
- We name the evidence your brand is missing today.
- You get the next step with the biggest effect. No obligation.